In this article
The current OpenAI documentation does not define detail: "high" on a PDF input_file as a vector-store indexing or file-search control. Instead, it describes three separate surfaces:
- Direct PDF input:
detailcontrols PDF page-image processing; extracted text remains included (OpenAI: File inputs). - Vector-store ingestion: adding a file automatically triggers chunking, embedding, and indexing (OpenAI: Retrieval).
- File-search retrieval:
vector_store_ids,max_num_results, andfiltersconfigure retrieval, while request-levelincludecan return the search results in the response (OpenAI: File search).
That separation is a documentation-based conclusion, not an experimental finding about undocumented internal behavior.
Field ownership at a glance
| Field or operation | Where it belongs | Documented effect | What it does not establish |
|---|---|---|---|
detail |
PDF input_file in the Responses API |
Controls PDF page-image processing (docs) | Changes to vector-store ingestion, embeddings, or search ranking |
| Add a file to a vector store | Vector-store ingestion | Automatically chunks, embeds, and indexes the file (docs) | Reuse of a direct-input detail value |
vector_store_ids |
file_search tool |
Selects the vector stores available to search (docs) | Changes to PDF page-image processing |
max_num_results |
file_search tool |
Limits the number of retrieved results (docs) | Ranking or answer-quality guarantees |
filters |
file_search tool |
Restricts results using file metadata (docs) | Automatic creation of that metadata |
include: ["file_search_call.results"] |
Responses API request | Includes file-search results in the response (docs) | Changes to retrieval or ranking |
This ownership map is more useful than treating every file-related field as part of one shared configuration. A file ID can appear in different operations, but that does not make the fields on those operations interchangeable.
What PDF detail controls
On vision-capable models, Responses API processing for a PDF extracts both text and page images and sends both to the model. The optional detail field changes how the page images are processed; it does not remove the extracted text (OpenAI: File inputs).
The documented values are:
auto, which is used when the field is omitted;low, which uses fewer input tokens;high, which provides more visual detail for material such as dense charts, small print, or diagrams.
The behavior of auto is model-dependent. It uses high for GPT-5.6 and later models and low for earlier models, according to the file-input guide (OpenAI: File inputs).
A direct PDF item can therefore contain:
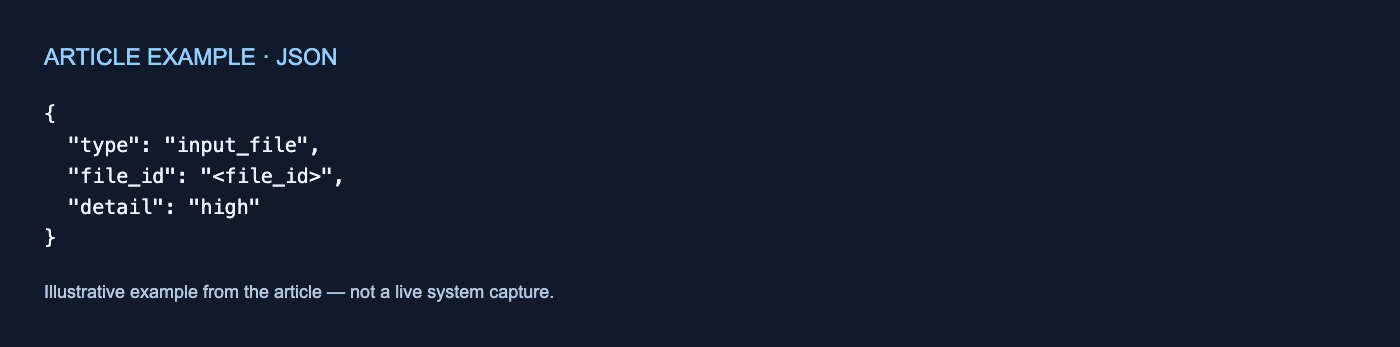
{
  "type": "input_file",
  "file_id": "<file_id>",
  "detail": "high"
}
In this request item, detail describes processing for the PDF’s page images. The cited documentation does not assign it a role in creating embeddings or determining search ranking. Chat Completions file inputs do not support this field; the documented PDF detail control belongs to Responses API input_file items (OpenAI: File inputs).
No quality, token, latency, or cost comparison was performed for the three detail values. The documentation describes their intended behavior, but that is not a measured prediction for a particular PDF or model.
Vector-store ingestion is a separate stage
Vector stores power semantic search for the Retrieval API and the file-search tool. When a file is added to a vector store, OpenAI documents an automatic ingestion process that chunks, embeds, and indexes the file (OpenAI: Retrieval).
The supplied documentation does not explain how this ingestion process handles PDF page images internally. It also does not connect the detail value from a direct Responses API input to vector-store ingestion. Consequently, detail: "high" should not be interpreted as an indexing-quality or embedding setting.
This distinction also prevents a common request-reading mistake: seeing the same uploaded file referenced in two places does not mean that configuration follows the file everywhere. The operation and field placement determine what is being configured.
A worked request-reading example
Consider an application with two independent actions.
First, it sends a PDF directly to a model to inspect a diagram:
{
  "type": "input_file",
  "file_id": "file_123",
  "detail": "high"
}
Read this as: process the PDF page images with high detail for this direct input while still including extracted text.
Separately, the application has added that file to a vector store and issues a search:
{
  "type": "file_search",
  "vector_store_ids": ["vs_123"],
  "max_num_results": 3,
  "filters": {
    "type": "in",
    "key": "category",
    "value": ["manual"]
  }
}
Read this second object without carrying over detail. It selects vs_123, limits retrieval to three results, and restricts eligible files by the category metadata. Those are file-search controls documented on the tool itself (OpenAI: File search).
If the surrounding Responses API request also contains:
{
  "include": ["file_search_call.results"]
}
the search results are included in the response. That field affects response inclusion; it is not documented as changing which results are retrieved or how they are ranked (OpenAI: File search).
Metadata must exist before it can filter
A filter operates on attributes assigned to vector-store files. The retrieval guide specifically warns that a custom filename attribute must be set explicitly; it does not automatically take the uploaded file’s name (OpenAI: Retrieval).
The same practical check applies to a filter such as category: "manual": the request can only filter on metadata available to the vector-store file. The documentation supports filtering, but it does not promise a ranking outcome after the filter is applied.
A compact diagnostic checklist
When reviewing a request, inspect each field where it appears:
- Under a PDF
input_file,detailgoverns page-image processing. - During vector-store ingestion, adding the file initiates chunking, embedding, and indexing.
- Inside
file_search,vector_store_idsselects stores,max_num_resultslimits results, andfiltersrestricts them by metadata. - At the Responses API request level,
includeexposesfile_search_call.results.
These documented boundaries do not provide quality, latency, cost, ranking, or persistence guarantees. No hands-on test was performed, and the cited pages do not rule out every undocumented internal interaction.
No comments yet