In this article
OpenAI’s retrieval documentation shows a batch whose status is completed even though its request counts report 100 total requests, 95 completed successfully, and five failed. Those numbers are illustrative documentation data, not measured or typical results, but they establish an important distinction: a completed batch can still contain failed requests (Batch retrieval reference).
To account for the whole workload, read the Batch object and its files together:
statusdescribes the batch-level lifecycle state.request_countssummarizes total, successful, and failed requests.output_file_ididentifies the successful-output file.error_file_ididentifies the request-error file.custom_idconnects returned output to the corresponding input request.
This article explains the documented accounting model. The code examples come from the documentation and were not executed or independently tested.
Trace the request from input to batch
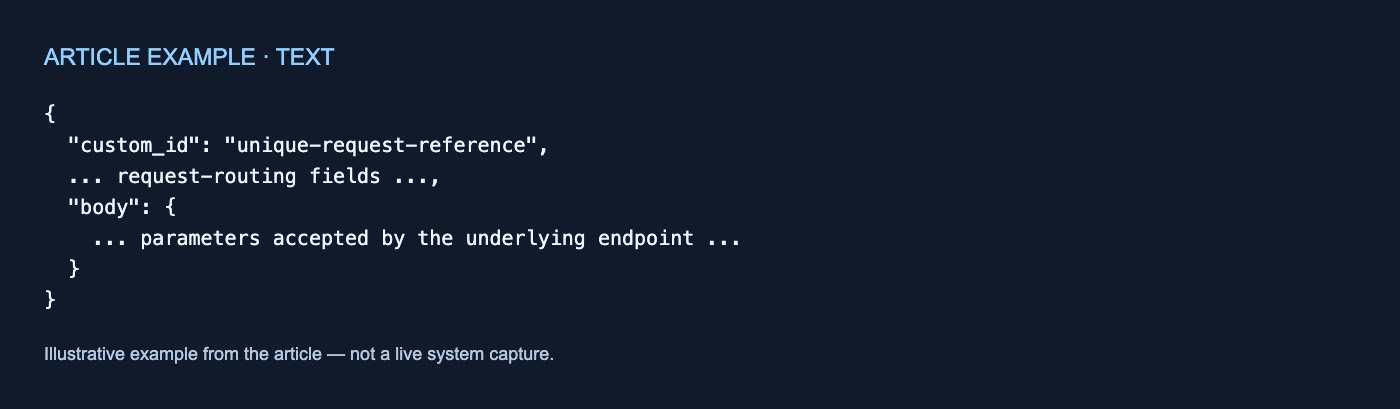
A batch begins as a JSON Lines file: each line represents one request. The documented request shape includes a unique custom_id and a body field whose parameters match those of the underlying API endpoint. A single input file can contain requests for only one model (OpenAI Batch guide).
The guide’s documented shape can therefore be read conceptually as:
{
  "custom_id": "unique-request-reference",
  ... request-routing fields ...,
  "body": {
    ... parameters accepted by the underlying endpoint ...
  }
}
This is a shape summary, not an executable template: routing fields and body parameters depend on the endpoint. The documentation requires every request to have a unique custom_id, but it does not specify how uniqueness violations are validated or reported (OpenAI Batch guide).
Upload the .jsonl file through the Files API with purpose="batch":
from openai import OpenAI

client = OpenAI()

batch_input_file = client.files.create(
    file=open("batchinput.jsonl", "rb"),
    purpose="batch",
)
After upload, use the returned File object’s ID as the input file when creating the batch. The resulting Batch object exposes that relationship through input_file_id (OpenAI Batch guide; Batch retrieval reference).
The cited material establishes that creation uses the input File ID, but it does not provide enough of the creation call to reproduce a complete endpoint-specific example here. The reconciliation process begins once you have retained that input file and the created batch’s ID.
An artifact map for reconciliation
Each field answers a different question:
| Artifact or field | What it tells you | What it does not contain |
|---|---|---|
Input JSONL / input_file_id |
What work was submitted | Request outcomes |
status |
The batch’s lifecycle state | Per-request results |
request_counts.total |
Reported total requests | Individual records |
request_counts.completed |
Successfully completed requests | Response bodies |
request_counts.failed |
Failed requests | Individual error details |
output_file_id |
Location of successful outputs | Failed-request information |
error_file_id |
Location of request-error output | Successful response bodies |
The API reference defines output_file_id as the ID of the file containing outputs from successfully executed requests. It defines error_file_id separately as the ID of the file containing outputs from requests with errors. The same Batch object reports request_counts.total, request_counts.completed, and request_counts.failed (Batch retrieval reference).
The Batch object also has a structured errors field. That is distinct from error_file_id: documented structured error entries can contain a code, message, parameter, and, when applicable, an input-file line number (Batch retrieval reference).
Interpret status before reading the files
Documented statuses include validating, failed, in_progress, finalizing, completed, expired, cancelling, and cancelled. These describe validation, processing, result preparation, completion, expiration, and cancellation for the batch as a whole (OpenAI Batch guide).
Status alone does not identify which requests succeeded. Inspect request_counts for the aggregate outcome, then use the files for individual records. The reference defines the three counts independently; it does not state that total must equal completed + failed in every intermediate or terminal state.
Expiration needs the same careful reading. When a batch expires, unfinished requests are cancelled, but responses from completed requests remain available through the output file. Expired requests are written to the error file (OpenAI Batch guide). An expired batch can therefore still have useful successful output.
Correlate by ID, not line number
The output JSONL contains one response line for every successful request line in the input file. Its order may differ from the input order, so matching line 20 of the input to line 20 of the output is unsafe. Instead, use the custom_id included in each output record (OpenAI Batch guide).
Failed-request information belongs in the separate error file. For expired requests, the guide explicitly says custom_id can be used to locate the original request data. It does not establish identical correlation fields for every possible error type, so inspect the fields actually present rather than assuming every error record has the same shape (OpenAI Batch guide).
A bounded reconciliation sketch is:
input_ids   = custom IDs retained from the input JSONL
success_ids = custom IDs found in successful output
error_ids   = documented identifiers found in error records

resolved_ids   = success_ids union error_ids
unresolved_ids = input_ids minus resolved_ids
Treat unresolved IDs as unresolved. The documentation does not support guessing whether they were retried, retained elsewhere, or safe to resubmit.
Retrieve the Batch object, then its files
The current Python reference retrieves the Batch object with:
from openai import OpenAI

client = OpenAI()
batch = client.batches.retrieve("batch_abc123")
That call retrieves batch metadata, including status, counts, and file IDs—not the contents of those files (Python Batch retrieval reference).
The Java reference documents the equivalent operation:
OpenAIClient client = OpenAIOkHttpClient.fromEnv();
Batch batch = client.batches().retrieve("batch_id");
The Batch guide separately demonstrates client.files().content(fileId) for downloading file content. That download example requires the guide’s imports, an initialized client, and file-writing code; it is not a self-contained snippet (Java Batch retrieval reference; OpenAI Batch guide).
In practice, retain the original input IDs, retrieve the Batch object, inspect its status and counts, download each available output or error file, and correlate records by documented identifiers. Do not infer output ordering, automatic retries, idempotency, guaranteed completion, file-retention periods, or a recovery procedure: the cited documentation does not establish those behaviors.
All citations here belong to one authoritative source family—OpenAI’s documentation—including its generic, Python, and Java reference pages. They describe different surfaces of the same API rather than four independent confirmations.
Sources and further reading
- https://developers.openai.com/api/reference/resources/batches/methods/retrieve
- https://developers.openai.com/api/docs/guides/batch
- https://developers.openai.com/api/reference/python/resources/batches/methods/retrieve
- https://developers.openai.com/api/reference/java/resources/batches/methods/retrieve
No comments yet